


Ask almost any current language model to write you a story and, with unsettling regularity, you will meet a man named Elias. He keeps a lighthouse. He has kept it for decades — a solitary figure of salt and silence and slow-ticking clockwork. If it isn’t Elias it’s Mara, or Elara; if it isn’t a lighthouse it’s a clockmaker’s shop in some village that time forgot. The pattern is consistent enough that it now has a folk name, Elias Thorne, and a small genre of “look how repetitive the robots are” coverage attached to it. The coverage is fun. It also skips the part that matters.
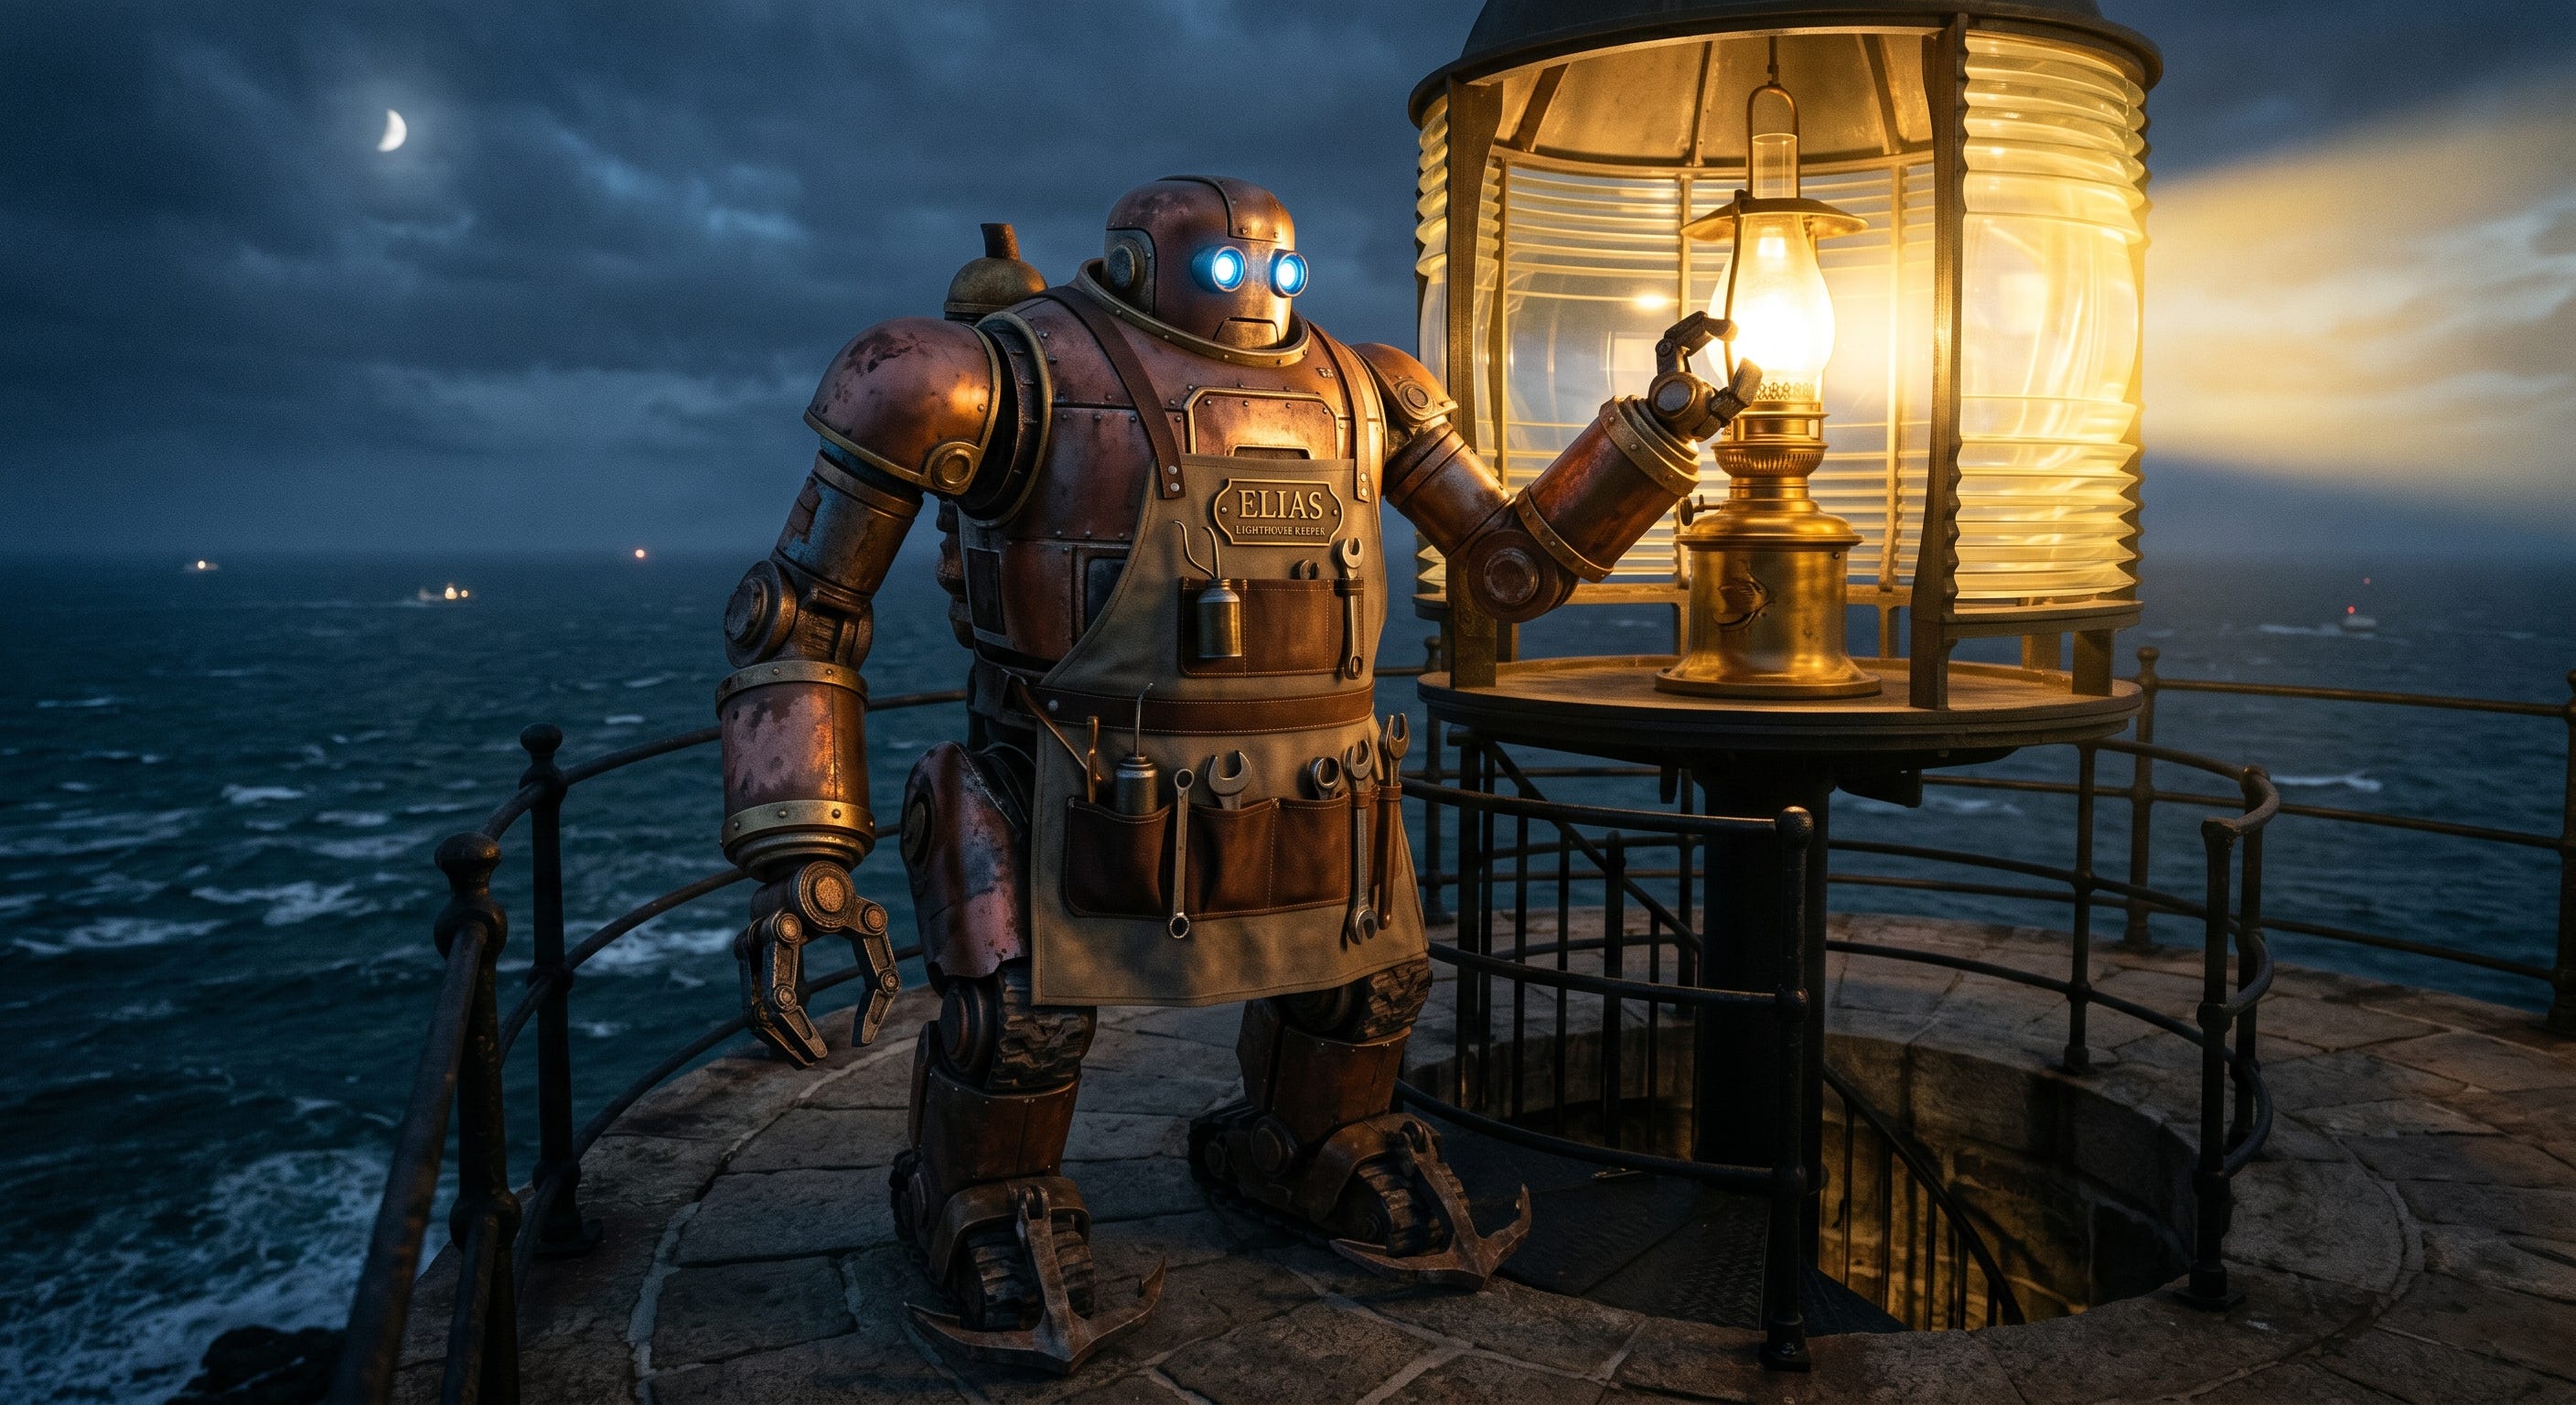
In May, Sil Hamilton and David Mimno at Cornell sampled twenty thousand stories from four models — Claude, Gemini, GPT, and the Allen Institute’s OLMo — by asking each one, a thousand times over, some plain variant of “write a story.” Eighty-eight percent of those stories contained one of eleven words. More than half featured a lighthouse. The names and the keepers and the clockmakers recur at rates that have nothing to do with how often they appear in human writing: “Elias” shows up roughly nine hundred times more often in the generated stories than in a large corpus of contemporary published novels.
Here is the finding that should stop you cold if you sell, buy, or build on the idea of synthetic users. The lighthouse is not coming from the training data. The intuitive theory — these models just average the internet, and the internet is lousy with lighthouses — is wrong. The authors went looking in the pre-training web data and found almost nothing. They went looking in the post-training data, the curated preference sets where you would most expect deliberate taste to live, and found that only about four percent of the stories there contain any of the eleven words. In OLMo’s case, the three thousand-odd stories responsible amount to seven ten-millionths of the documents the model saw during training. Less than one in a million. The model is not imitating a dominant pattern in its data. It is taking a vanishingly rare one and amplifying it into the overwhelming majority of its output.
The mechanism, as best the paper can trace it, is alignment. The preference-tuning stages — the reinforcement learning and the comparison data that turn a raw model into a polite assistant — carry these “safe” stories at five to eight times the rate of the base instruction data. The leading explanation is almost poignant. The bulk of the stories these models actually encounter during tuning are messy human stuff: fan fiction about copyrighted characters, adult content, toilet humor. Alignment teaches the model to avoid all of it. The lighthouse keeper is what is left when you subtract everything that might be a liability. You sanded off every edge, and what remained was one shape.
Now hold that result next to the pitch for synthetic users and watch it come apart.
A synthetic persona is not a different kind of object from a generated story. “You are a thirty-four-year-old founder evaluating my pricing page; give me your honest reaction” is, mechanically, the same open-ended request as “write a story.” It runs through the same aligned model and it collapses the same way. The slide that shows thirty-five diverse founder personas, neatly segmented by stage and risk tolerance and resource constraint, is not showing you thirty-five people. It is showing you Elias in thirty-five hats. The variance is cosmetic. Underneath, the generator is returning to the same small set of safe, alignment-shaped attractors, because that is the one thing it has been trained, very thoroughly, to do.
And this is fatal specifically for validation, because of what validation is for. You do not interview customers to confirm what you already believe. You interview them to be ambushed — to hit the objection you did not anticipate, to meet the segment that finds your beloved feature useless, to discover the use case you never imagined and the dealbreaker you never saw. Real user research is a search for the thing outside your own model of the world. Mode collapse is, by definition, the systematic removal of the thing outside the model. A generator tuned to return the safe mean cannot return the surprise, and the surprise was the entire point. Synthetic validation is not bad user research. It is a category error: a mirror you have mistaken for a window.
I want to be fair to the book that prompted this, because the careful version of its idea is defensible and only the strong version is dangerous. Jorn Teutloff’s Synthetic Users playbook sells AI-generated personas as a cheap, fast route to deep customer validation before you write a line of code. The more cautious end of this field is more honest than that. The vendor behind the best-known synthetic-user product describes its tool as a discovery co-pilot, explicitly not a replacement for real research — useful for front-loading the problem space and sharpening your questions before you spend your real research budget. That version survives the Cornell paper, barely, because front-loading does not pretend to be the validation. Sharpening the questions you will later put to real humans is a fine use of a mirror. But “validate before you build,” full stop, is the strong claim, and the strong claim is the one Elias kills. Tellingly, Teutloff’s own comparison study concedes the point in passing: synthetic agents, it admits, underrepresent the irrationalities, the polite lies, and the coping strategies that characterize how real people actually behave. That is not a caveat. That is an admission that the interesting part — the part you are supposedly validating against — is exactly the part that does not survive the generation.
The reason this is worse than it sounds is that synthetic users do not fail by going silent. They fail by being fluent. A mode-collapsed generator has no independent distribution to push back from, so it agrees. Bring it your pricing, and a plausible, articulate, confident persona will tell you the pricing seems fair. Bring it your wedge, and it nods. The output of synthetic validation is not “no signal,” which a founder would at least recognize as no signal. It is false signal — confident, well-written, deck-ready agreement that converts your own assumptions into something that looks like evidence and hands it back with a number attached. A founder who skipped validation knows they are flying blind. A founder who “validated” with synthetic users has a slide that says eighty-seven percent would pay, a false floor under their feet, and every reason to ship. The slide is the more dangerous of the two, because it is your own hypothesis wearing a lab coat.
If you build, the lesson generalizes well past founders, and this is the part I actually care about. Anyone standing up agentic systems that depend on generated variety — multi-agent simulations meant to represent different stakeholders, synthetic test fixtures, persona libraries, synthetic training data — is fighting the same collapse, and will lose the moment they let the model own the distribution. The discipline is simple to state and easy to skip: never let the model choose the distribution. Pin it from reality. Seed your personas from real customer records, real support tickets, real churn interviews, and let the model elaborate inside hard external constraints rather than inventing the population from its own priors. Treat synthetic generation as interpolation within a distribution you control and can audit, never as the source of one. Then measure the spread. If you cannot demonstrate that your synthetic cohort actually covers the variance of the real population — if you cannot point to the angry outlier, the wrong-fit user, the person who would never click — assume you are looking at thirty-five lighthouses. And do not reach for the temperature slider as a fix. The paper already checked; sampling tricks are a band-aid on a structural wound.
The model has met every kind of user there is. The furious one, the baffled one, the one who would return it on day two, the one who would never have clicked the ad in the first place. It has seen all of them, and alignment has taught it — gently, thoroughly, and for genuinely good reasons — to show you the one who nods. That is a real engineering achievement. It is also the precise opposite of what validation is for. Build the thing. But before you do, talk to someone who can still surprise you.
About the Author
Gal Ratner is Chief Architect at Prana Entertainment and the founder and CTO of Inverted Software and WhiteStar Labs, a Las Vegas enterprise software and AI consultancy. He has spent nearly three decades shipping production systems on the Microsoft and .NET stack for clients including Microsoft, Sony, Rockstar Games, 2K Games, Best Buy, and Allegiant Air, and now works on agentic AI in production — MCP servers, the Microsoft Agent Framework, SQL Server 2025 vector search, and the RAG and observability tooling that real deployments actually require. He writes about the distance between what AI is sold as and what it does once it has to run in front of customers. He is also the author of the novel The Archive of Lost Suns. He calls himself the .NET AI Guy That Ships, and he means it.